Data Ingestion Bottlenecks & Labeling Delays
Unstructured raw data, missing annotations, and fragmented preprocessing scripts stall ML workflows before model training even begins.
Enterprise machine learning development platform engineered to accelerate data pipeline orchestration, distributed model training, hyperparameter optimization, and automated MLOps deployment. Build and scale production-ready models from a single unified workspace.
Our complete Machine Learning Development platform solves the real infrastructure bottlenecks of modern AI teams, turning raw data into production-grade models faster.
Unstructured raw data, missing annotations, and fragmented preprocessing scripts stall ML workflows before model training even begins.
Unoptimized training jobs and idle cloud instances inflate development expenses without delivering measurable performance gains.
Without automated experiment logging, data scientists lose track of hyperparameters, metrics, and dataset splits, killing reproducibility.
Packaging models manually into production containers leads to dependency mismatches, slow rollout cycles, and deployment errors.
Live data distributions shift over time, causing unmonitored production models to silently degrade and generate inaccurate predictions.
Unoptimized model weights and poor serving architectures cause slow API response times, failing critical real-time application SLAs.
Differences between offline training pipelines and online feature generation introduce subtle bugs that compromise real-world model accuracy.
Without strict model lineage, artifact hashing, and explainability records, organizations fail AI security audits and regulatory compliance.
Disconnected collaboration between researchers and MLOps engineers results in delayed handoffs, misaligned environments, and lost productivity.
Our Machine Learning Development platform integrates feature engineering, distributed training, hyperparameter tuning, model registry, and MLOps deployment into a single unified workflow. Real-time telemetry and pipeline automation help engineering teams eliminate training bottlenecks, minimize latency, and deploy high-accuracy models to production faster.
Streamline data ingestion across data lakes, warehouses, and streaming sources while managing annotation workflows and validation rules with complete data lineage.
Maintain centralized feature stores with version control, automated schema validation, and consistency checks to prevent train-serve skew in production models.
Track raw datasets, transformation pipelines, training splits, and model checkpoints across development environments to ensure full reproducibility.
Scale deep learning and machine learning workloads across multi-node GPU clusters, optimizing batch sizes and compute parallelization for faster iteration cycles.
Leverage Bayesian optimization and early-stopping algorithms to explore hyperparameter search spaces dynamically and extract peak model performance.
Package validated model artifacts, dependency lockfiles, and containerized serving endpoints for deterministic, push-button staging deployments.
Monitor inference latency, prediction accuracy, GPU utilization, and API endpoint availability through granular, real-time observability dashboards.
Detect feature distribution shifts, statistical anomalies, and concept degradation early to trigger automated retraining pipelines before accuracy drops.
Transform production inference feedback into iterative optimization cycles, automating model updates to maintain state-of-the-art inference quality.
Discover the enterprise-grade capabilities of our Machine Learning Development platform, engineered to accelerate model training, automate CI/CD pipelines, and deliver high-precision inference at scale.
Our machine learning platform operationalizes every phase of the AI lifecycle, from raw data preparation and distributed training to automated model evaluation, deployment, and live inference monitoring.
Streamline raw data extraction, cleaning, automated labeling, and feature engineering. Standardize data pipelines to feed production-grade training algorithms seamlessly.
Log hyperparameter configurations, dataset versions, code commits, and evaluation metrics automatically. Guarantee full reproducibility across every training run.
Scale model training across multi-node GPU clusters using automated Bayesian search algorithms. Maximize compute utilization while accelerating convergence speeds.
Monitor live inference latency, prediction accuracy, and data distribution shifts in real time. Detect concept drift instantly and trigger automated retraining alerts.
Validate precision, recall, F1 scores, and inference latency against production thresholds before deployment. Benchmark challenger models against existing champions.
Store, version, and stage model artifacts with production-readiness tags, cryptographic checksums, and dependency lockfiles for governed release management.
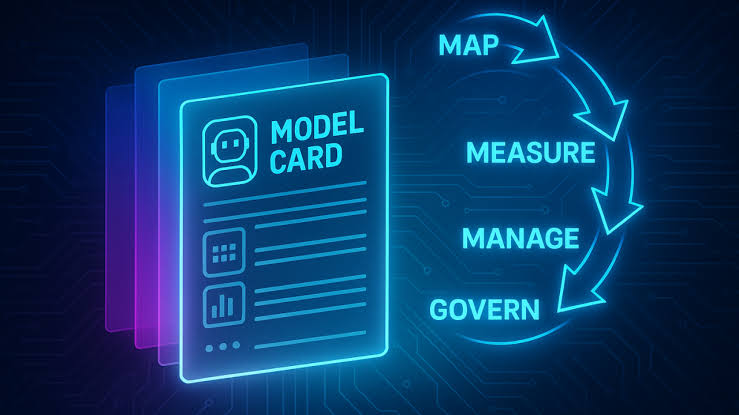
Automate technical documentation by generating standardized model cards, fairness evaluations, training data summaries, and bias audit reports instantly.
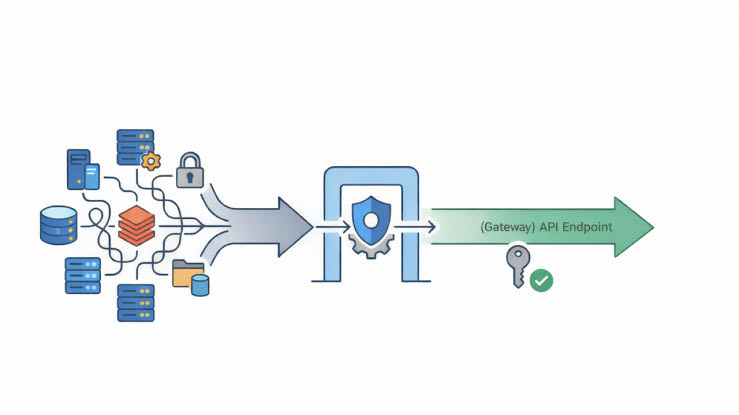
Deploy models as scalable REST and gRPC endpoints across hybrid cloud clusters with automated load balancing, batch inference, and autoscaling.
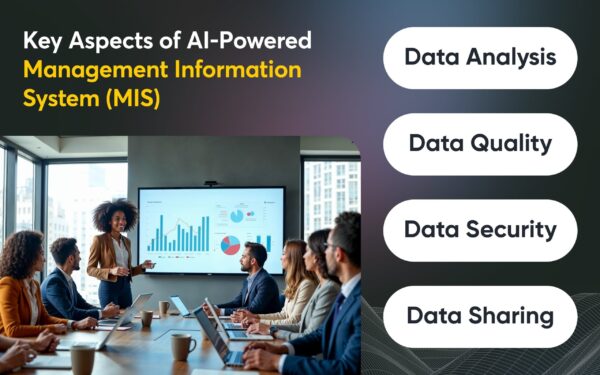
Gain complete transparency over your AI stack with centralized MIS reports. Track compute ROI, API throughput, model accuracy degradation, and team velocity in real time.
Accelerate enterprise AI initiatives by operationalizing data pipelines, automating model training, and streamlining MLOps across hybrid cloud environments.
Transform raw datasets into high-signal training features automatically. Standardize feature engineering and eliminate train-serve skew effortlessly.
Log hyperparameters, code commits, and metric curves automatically to ensure reproducible model training across every research experiment.
Track complete data provenance, artifact dependencies, and compliance metadata across the machine learning lifecycle in just a few simple clicks.
Validate model accuracy, latency, and fairness against test baselines before production deployment with customizable evaluation pipelines.
Empower cross-functional engineering teams with shared notebook environments, centralized model registries, and real-time project sharing.
Allocate GPU and TPU clusters dynamically, optimize training infrastructure costs, and manage hardware instances through automated cluster scaling.
Data ingestion, distributed model training, and continuous deployment run together seamlessly—shortening experimentation cycles, reducing cloud compute costs, and keeping model governance under control without friction.
Define ML Use Cases
& Data Architecture
Engineer Features
& Ingest Datasets
Train
& Tune Models on GPU
Deploy Scalable Inference Endpoints
Integrate APIs with Core Business Apps
Monitor Drift
& Business Impact
GCTL Machine Learning Development Software combines automated pipeline orchestration with scalable GPU acceleration to streamline training workflows, eliminate experiment tracking errors, reduce compute costs, and elevate enterprise AI performance.
Smart Bayesian algorithms analyze hyperparameter spaces, loss curves, and resource constraints to eliminate configuration bottlenecks and automate optimal model convergence.
Live engineering dashboards monitor training runs, dataset versions, validation benchmarks, and cluster deployment status without fragmented scripts.
Centralize training features, model binaries, and evaluation metadata in a secure cloud ecosystem, providing data scientists instant access anywhere.
Instantly convert validated model checkpoints into scalable REST and gRPC inference microservices, eliminating engineering handoff delays.
Seamless integration with cloud providers dynamically allocates spot instances, tracks per-job compute expenditures, and maximizes hardware utilization.
Streamline model validation with automated confusion matrices, ROC-AUC scoring, latency profiles, and instant fairness compliance documentation.
Built-in observability monitors distribution shifts, prediction degradation, inference latencies, and triggers automated retraining alerts directly to engineers.
Empower researchers and DevOps specialists to share interactive notebooks, review model dependencies, track pipeline runs, and inspect models on the go.
Evaluate overall AI project success with comprehensive reporting on cluster throughput, model accuracy degradation, cloud expenditures, and business impact metrics.
Chief Technology Officer / Fintech Founder
Partnering with their custom software development team completely revamped our core transaction engine. Migrating away from rigid off-the-shelf tools to a high-throughput microservices architecture was flawless. Our automated API pipelines now process millions in daily volume with zero latency.
VP of Product / Enterprise SaaS Director
Their agile engineering expertise and technical discovery process gave us complete clarity from sprint zero. The custom multi-tenant architecture and CI/CD pipelines they implemented cut our feature release cycles in half. Their dedicated engineering team sets the gold standard for full-stack delivery.
Head of Digital Transformation / HealthTech CEO
The custom platform they engineered exceeded every strict regulatory and compliance benchmark we needed, including HIPAA and SOC 2. They modernized our legacy databases into an intuitive, secure cloud system that our operations team adopted effortlessly on day one.
Chief Operating Officer / Logistics Enterprise
We needed a tailor-made ERP solution to unify global supply chain tracking, automated invoicing, and real-time fleet analytics under one roof. Their custom software solution delivered precisely that, saving us thousands in recurring licensing overhead while scaling our operations seamlessly.
Enterprise ML Platform For High-Performance Feature Engineering, Distributed Training, and Automated MLOps Monitoring
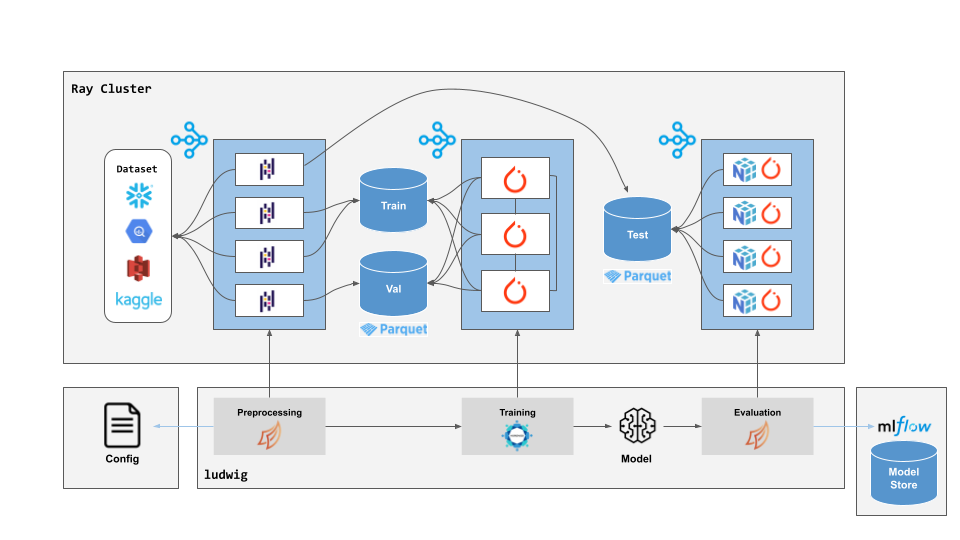
It is an end-to-end software ecosystem where data scientists and engineers build, train, evaluate, deploy, and monitor AI models collaboratively—integrating data pipelines, feature stores, GPU compute, and model registries into a unified architecture.
Our platform enables production deployments within days rather than months. With automated containerization, pre-configured CI/CD pipelines, and standardized API gateways, your engineering team can move from prototype to scalable inference endpoints seamlessly.
It continuously monitors live inference traffic for data drift, concept degradation, and latency spikes. Automated alerting and continuous retraining triggers ensure production models maintain optimal predictive accuracy without manual engineering intervention.
Essential features include a centralized feature store, automated experiment tracking, distributed GPU orchestration, model versioning, low-latency model serving, and robust security governance with complete data lineage tracking.
It drastically reduces time-to-market for AI products, cuts cloud compute expenditure through dynamic GPU cluster allocation, and prevents revenue loss caused by silent model decay in high-volume enterprise production environments.