Provider Rate Limits & Unplanned Outages
Relying on a single foundation model provider exposes your application to sudden API downtime, rate limit throttling, and severe user-facing service disruptions.
Unified model orchestration framework engineered to automate dynamic prompt routing, slash token costs, enforce guardrails, and prevent latency spikes. Supercharge your AI engineering and scale production workloads across leading model providers.
Our Model Orchestration Platform is engineered specifically to eliminate latency bottlenecks, slash runaway token costs, and guarantee high availability across complex AI architectures.
Relying on a single foundation model provider exposes your application to sudden API downtime, rate limit throttling, and severe user-facing service disruptions.
Sending every prompt to expensive flagship models without semantic evaluation or caching inflates token consumption and burns through engineering budgets.
Without granular telemetry on time-to-first-token and intermediate agent step latencies, engineering teams struggle to diagnose and resolve performance bottlenecks.
Evaluating model releases, prompt versions, and fine-tuned weights by hand wastes developer hours, increases regression risks, and delays critical feature releases.
Lack of multi-tenant rate limits and cost controls allows unmonitored queries to generate unexpected cloud bills, severely straining operational margins.
Without automated guardrails and verification layers, inconsistent model outputs reach end users, creating compliance vulnerabilities and degrading brand trust.
Hardcoded agent workflows and bespoke API wrappers break easily when provider schemas change, leading to complex pipeline failures and continuous maintenance debt.
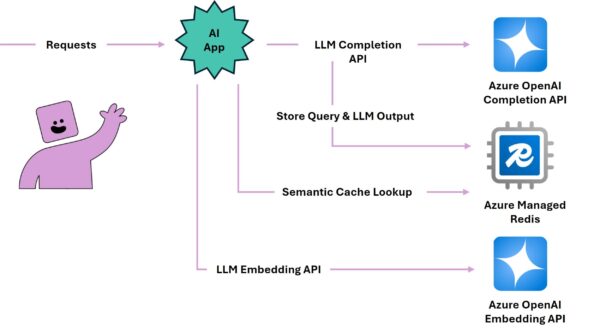
Without semantic caching layers, identical user prompts trigger repetitive model inferences, inflating latency and driving up cloud infrastructure expenses.
When vector stores, agent runtimes, and external APIs operate without centralized tracing, developers lack unified telemetry to monitor and optimize system health.
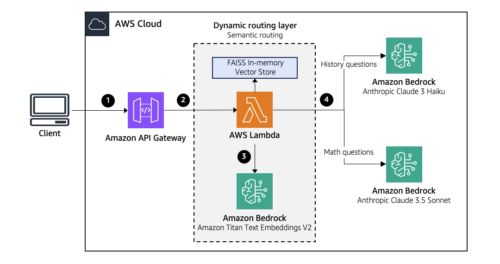
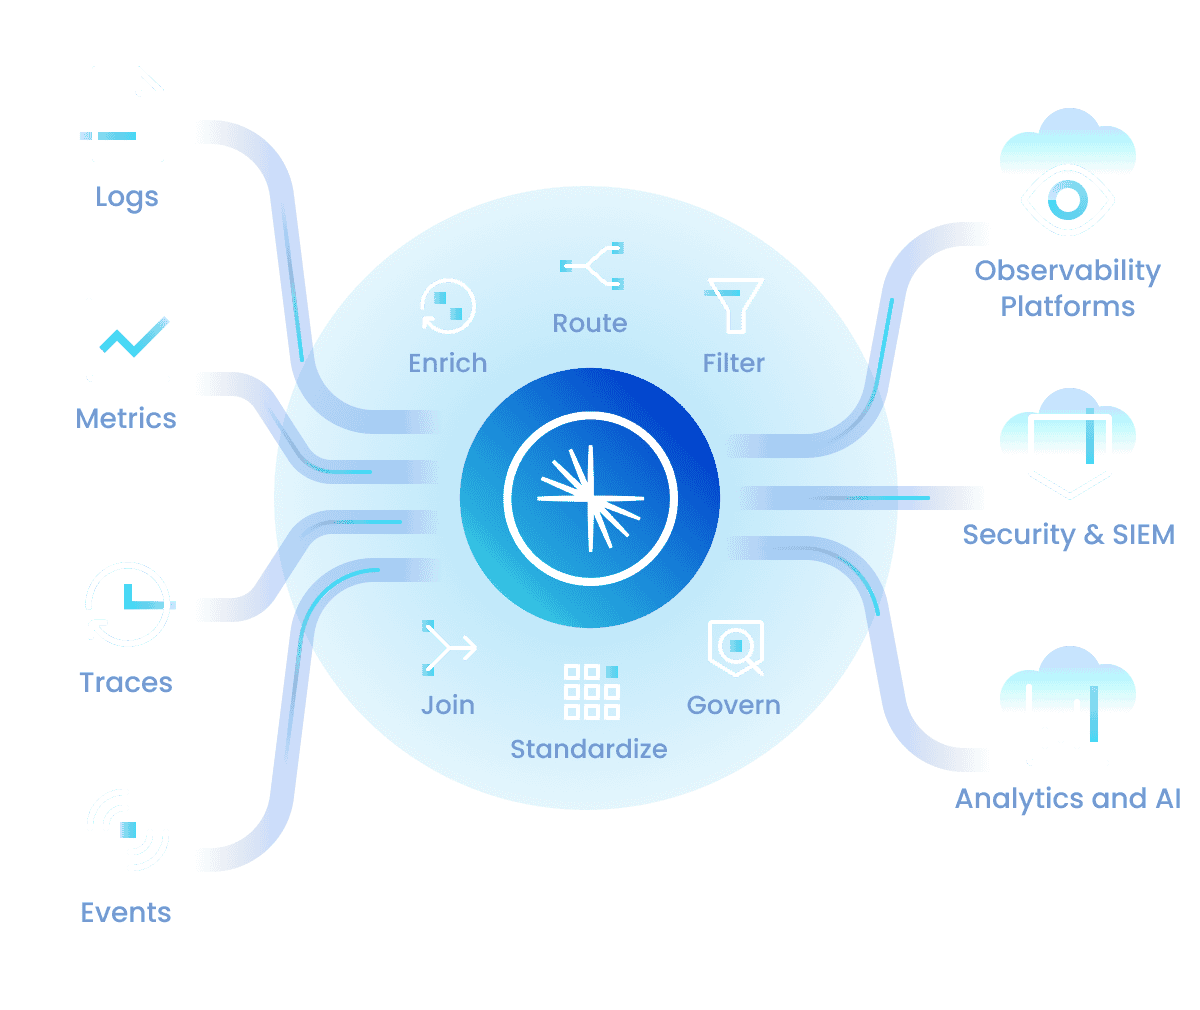
Our Model Orchestration Platform seamlessly coordinates multi-LLM routing, context enrichment, fallback cascades, guardrail checks, and inference caching through one unified runtime. Leverage dynamic intelligence to eliminate latency spikes, slash token overhead, and deploy resilient AI applications at enterprise scale.
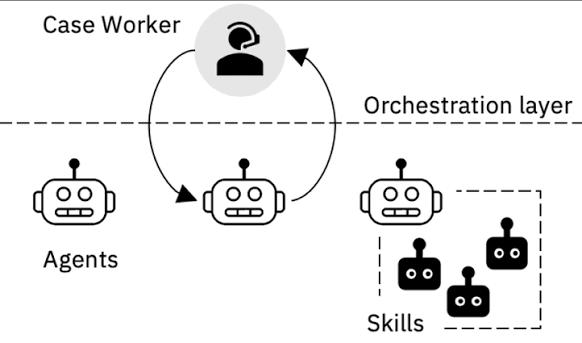
Standardize API endpoints, manage provider keys, unify schema formats, and coordinate multi-agent chains in real time for absolute control across your entire AI model ecosystem.
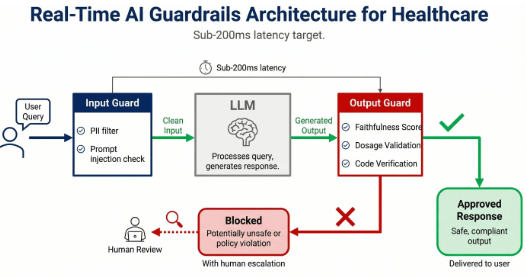
Enforce PII redaction rules, content moderation checks, and hallucination filters automatically across incoming prompts and model responses to satisfy strict enterprise security standards.
Track embedding pipelines, index vector chunks, optimize retrieval context, and route knowledge-base queries across distributed clusters to eliminate hallucinated outputs and retrieval lag.
Evaluate token lengths, prompt complexity, and provider quotas dynamically to dispatch inference jobs to the fastest and most cost-effective foundation models in real time.
Assign self-hosted open-source models, proprietary frontier APIs, and specialized fine-tuned weights dynamically based on live server loads to eliminate infrastructure bottlenecks.
Trigger instantaneous fallback chains during third-party API outages or rate limit breaches, automatically rerouting traffic to backup models without interrupting user sessions.
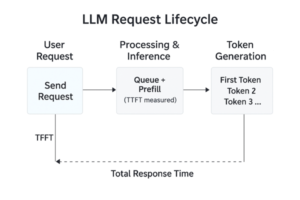
Monitor token consumption, time-to-first-token (TTFT), error frequencies, and agent step latencies across production environments through unified analytical dashboards.
Analyze prompt token usage, completion expenses, cache hit ratios, and multi-tenant billing allocations to enforce budget limits and prevent runaway API expenditure.
Transform telemetry data into actionable intelligence to benchmark model accuracy, optimize prompt templates, fine-tune smaller models, and scale generative AI operations efficiently.
Discover the enterprise capabilities of our Model Orchestration platform, engineered to streamline multi-LLM routing, boost inference performance, and drive generative AI reliability.
Our model orchestration platform connects your end-to-end AI architecture, from dynamic multi-LLM routing and prompt engineering to semantic caching, automated fallbacks, and real-time observability.
Route incoming user prompts, classify task complexity, balance provider traffic, and enforce token parameters in one runtime. Keep inference costs optimized from ingestion to generation.
Store similar queries, cache embedding vectors, reduce duplicate model calls, and index knowledge bases. Slash token overhead and improve response latency across production workloads.
Configure provider fallbacks, retry policies, and secondary model endpoints using an automated failover engine. Maximize uptime and eliminate downtime risks across distributed pipelines.
Monitor token generation speed, TTFT metrics, and agent step latencies in real time. Identify performance bottlenecks instantly and stream telemetry data to developer dashboards.
Enforce token budgets, track API key usage, allocate project expenses, and apply rate limits dynamically. Prevent cloud cost overruns and align spend with real-time application demand.
Validate prompt inputs, redact sensitive PII, filter malicious injections, and score output factualness with automated safety guardrails. Ensure high response accuracy across all models.
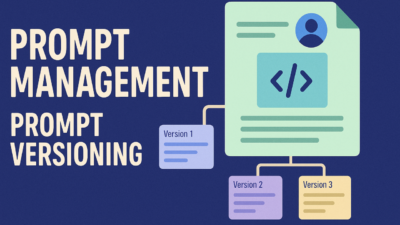
Simplify AI workflow iterations by managing prompt variations, parameter sets, context schemas, and version branches directly through a centralized developer workspace.
Coordinate function calling, tool execution pipelines, external API integrations, memory retention, and agent collaboration for complex multi-step generative workflows.
Gain complete transparency over your AI stack with centralized telemetry and analytics. Track token throughput, provider uptime, accuracy benchmarks, and cost efficiency from one dashboard.
Our Model Orchestration Platform integrates multi-LLM routing, dynamic inference pipelines, and automated failover to eliminate latency spikes and slash inference costs.
Dynamically route user prompts to the most cost-effective LLMs based on task complexity, context window size, real-time token pricing, and response speed.
Ensure zero application downtime with instant model failovers that reroute traffic around provider rate limits, API outages, and token throttle thresholds.
Track input prompts, latency breakdowns, output tokens, and execution paths across complex multi-agent chains to debug regressions in a few clicks
Benchmark model accuracy, detect hallucinations, and enforce content safety guardrails before deploying new fine-tuned weights or prompt templates to production.
Standardize multi-provider integrations under a single universal API gateway, enabling development teams to build, chain, and scale AI agents effortlessly.
Cache recurring semantic queries, eliminate duplicate model inferences, and cut LLM operational expenditure by up to 60% with automated vector indexing.
Dynamic routing, prompt caching, and automated failover run together seamlessly, keeping inference latency ultra-low, token expenditure strictly controlled, and enterprise reliability guaranteed without extra engineering overhead.
Define Multi-LLM Routing Strategy
Analyze Prompt
& Token Complexity
Configure Gateways
& Safety Guardrails
Deploy Orchestration Runtime Engine
Integrate Al Agents, RAG
& Microservices
Track Latency, Cost
& Token Metrics
GCTL Model Orchestration Platform combines intelligent multi-LLM routing with real-time inference observability to streamline AI workflows, slash token expenses, eliminate provider downtime, and elevate production model performance.
Smart routing algorithms evaluate prompt intent, context window size, and latency constraints to eliminate bottlenecks and automate cost-optimal foundation model selection.
Live developer dashboards monitor token throughput, TTFT latency, error rates, and API provider health metrics without complex custom telemetry pipelines.
Cloud AI Orchestration Runtime & Semantic Cache Repository Centralize prompt templates, embedding vectors, model weights, and context indexes in a high-speed cache layer, providing AI agents instant retrieval anywhere.
Instantly redirect throttled API requests to backup model providers or self-hosted instances during outages, eliminating service interruptions seamlessly.
Seamless integration with enterprise billing systems automatically enforces token quotas per project and provides granular financial chargebacks across departments.
Streamline prompt testing with automated regression suites, semantic similarity scores, latency benchmarks, and instant accuracy evaluation reports.
Built-in inspection pipelines filter prompt injections, redact confidential PII, detect factual drift, and trigger instant compliance alerts before generation completes.
Empower AI engineers and admins to track inference traffic, manage API keys, inspect failed traces, and adjust rate limits on the go from any mobile device.
Evaluate AI unit economics with comprehensive reporting on token consumption rates, cache savings, model provider billing, and seasonal inference trends.
Chief Technology Officer / Fintech Founder
Partnering with their custom software development team completely revamped our core transaction engine. Migrating away from rigid off-the-shelf tools to a high-throughput microservices architecture was flawless. Our automated API pipelines now process millions in daily volume with zero latency.
VP of Product / Enterprise SaaS Director
Their agile engineering expertise and technical discovery process gave us complete clarity from sprint zero. The custom multi-tenant architecture and CI/CD pipelines they implemented cut our feature release cycles in half. Their dedicated engineering team sets the gold standard for full-stack delivery.
Head of Digital Transformation / HealthTech CEO
The custom platform they engineered exceeded every strict regulatory and compliance benchmark we needed, including HIPAA and SOC 2. They modernized our legacy databases into an intuitive, secure cloud system that our operations team adopted effortlessly on day one.
Chief Operating Officer / Logistics Enterprise
We needed a tailor-made ERP solution to unify global supply chain tracking, automated invoicing, and real-time fleet analytics under one roof. Their custom software solution delivered precisely that, saving us thousands in recurring licensing overhead while scaling our operations seamlessly.
Enterprise-Grade Model Orchestration Platform For Dynamic Multi-LLM Routing, Latency Optimization, and Real-Time AI Observability
It is a unified runtime middleware layer that connects, coordinates, and manages multiple foundation models and SLMs—handling dynamic request routing, context enrichment, fallback logic, rate limits, and safety guardrails across your entire AI stack.
Our universal API gateway is OpenAI-compatible and can be deployed within minutes using a single endpoint change. Full enterprise configuration—including custom fallback routing rules, semantic caching layers, and guardrail policies—typically takes just a few days.
It intelligently classifies incoming prompt intent and routes simpler tasks to lightweight, cost-effective models while reserving expensive frontier LLMs strictly for complex reasoning. Combined with semantic caching, this reduces overall token expenditure by up to 60%.
Essential features include multi-provider load balancing, automated zero-downtime failover, semantic vector caching, streaming token telemetry, hallucination detection guardrails, and centralized API key governance with granular usage analytics.
It eliminates vendor lock-in, shields your applications from upstream provider outages, enforces enterprise safety policies, and optimizes latency and token budgets—giving engineering teams full visibility and control over generative AI systems.